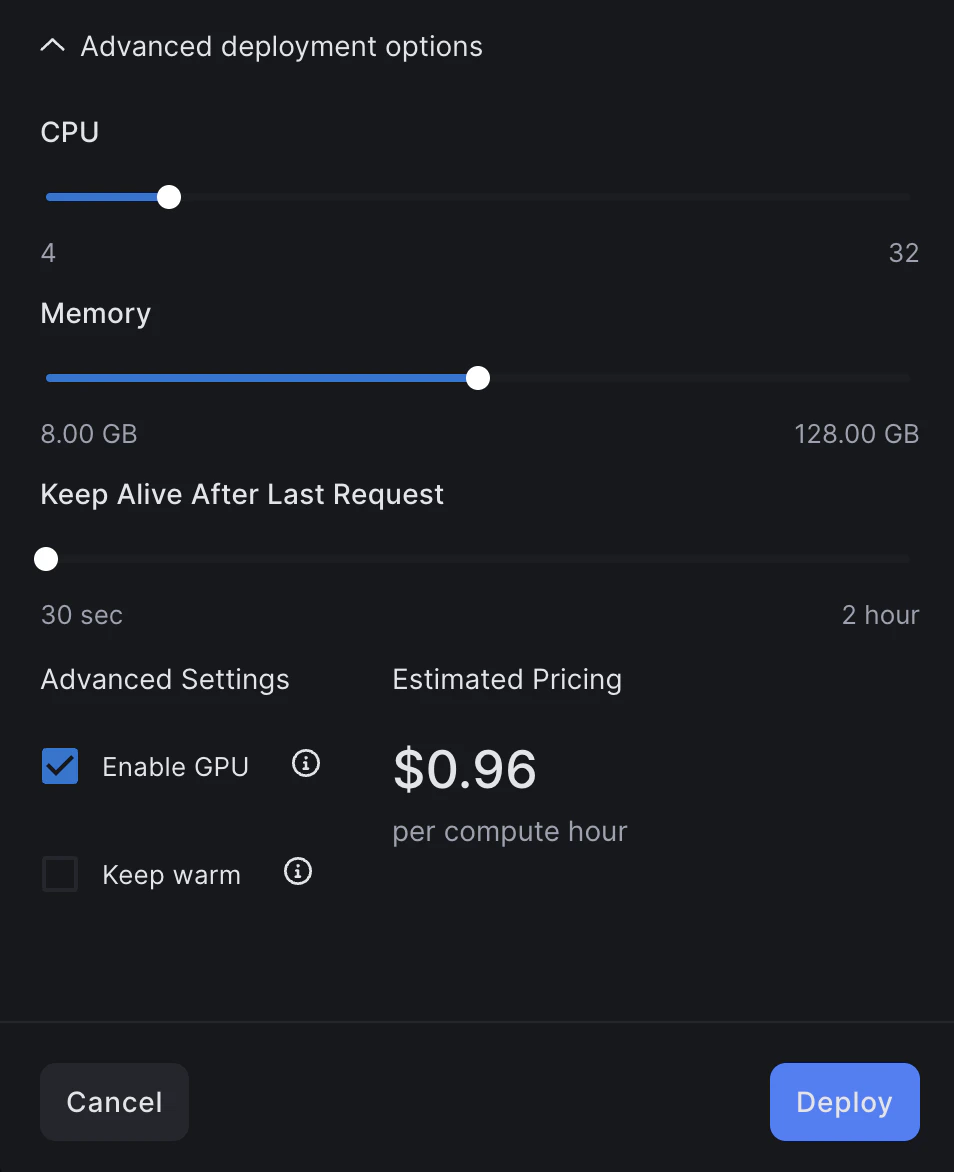
You can configure the machine for your model deployment by clicking Advanced deployment options in the deployment modal.You may wish to do things like:
Deploy your model on a GPU
Keep your model warm to eliminate the serverless cold start
Configure the CPU and Memory available on your deployment
Configure how long to wait before scaling your deployment down to zero after the last request
Assistant
Responses are generated using AI and may contain mistakes.